CHUNKS DANCE
EMOTIONIFICATION: Create three points of resonance where movement, sound, and emotion come together.
Voice Cloning in Chunks Theory is more than technology — it is voice-tuning for identity. Through a personalized podcast, guided mirror talk, and conversation with CHUNKS GPT, learners hear their own future-aligned voice. This creates a feedback loop where sound reshapes confidence, resonance, and fluency from the inside out.

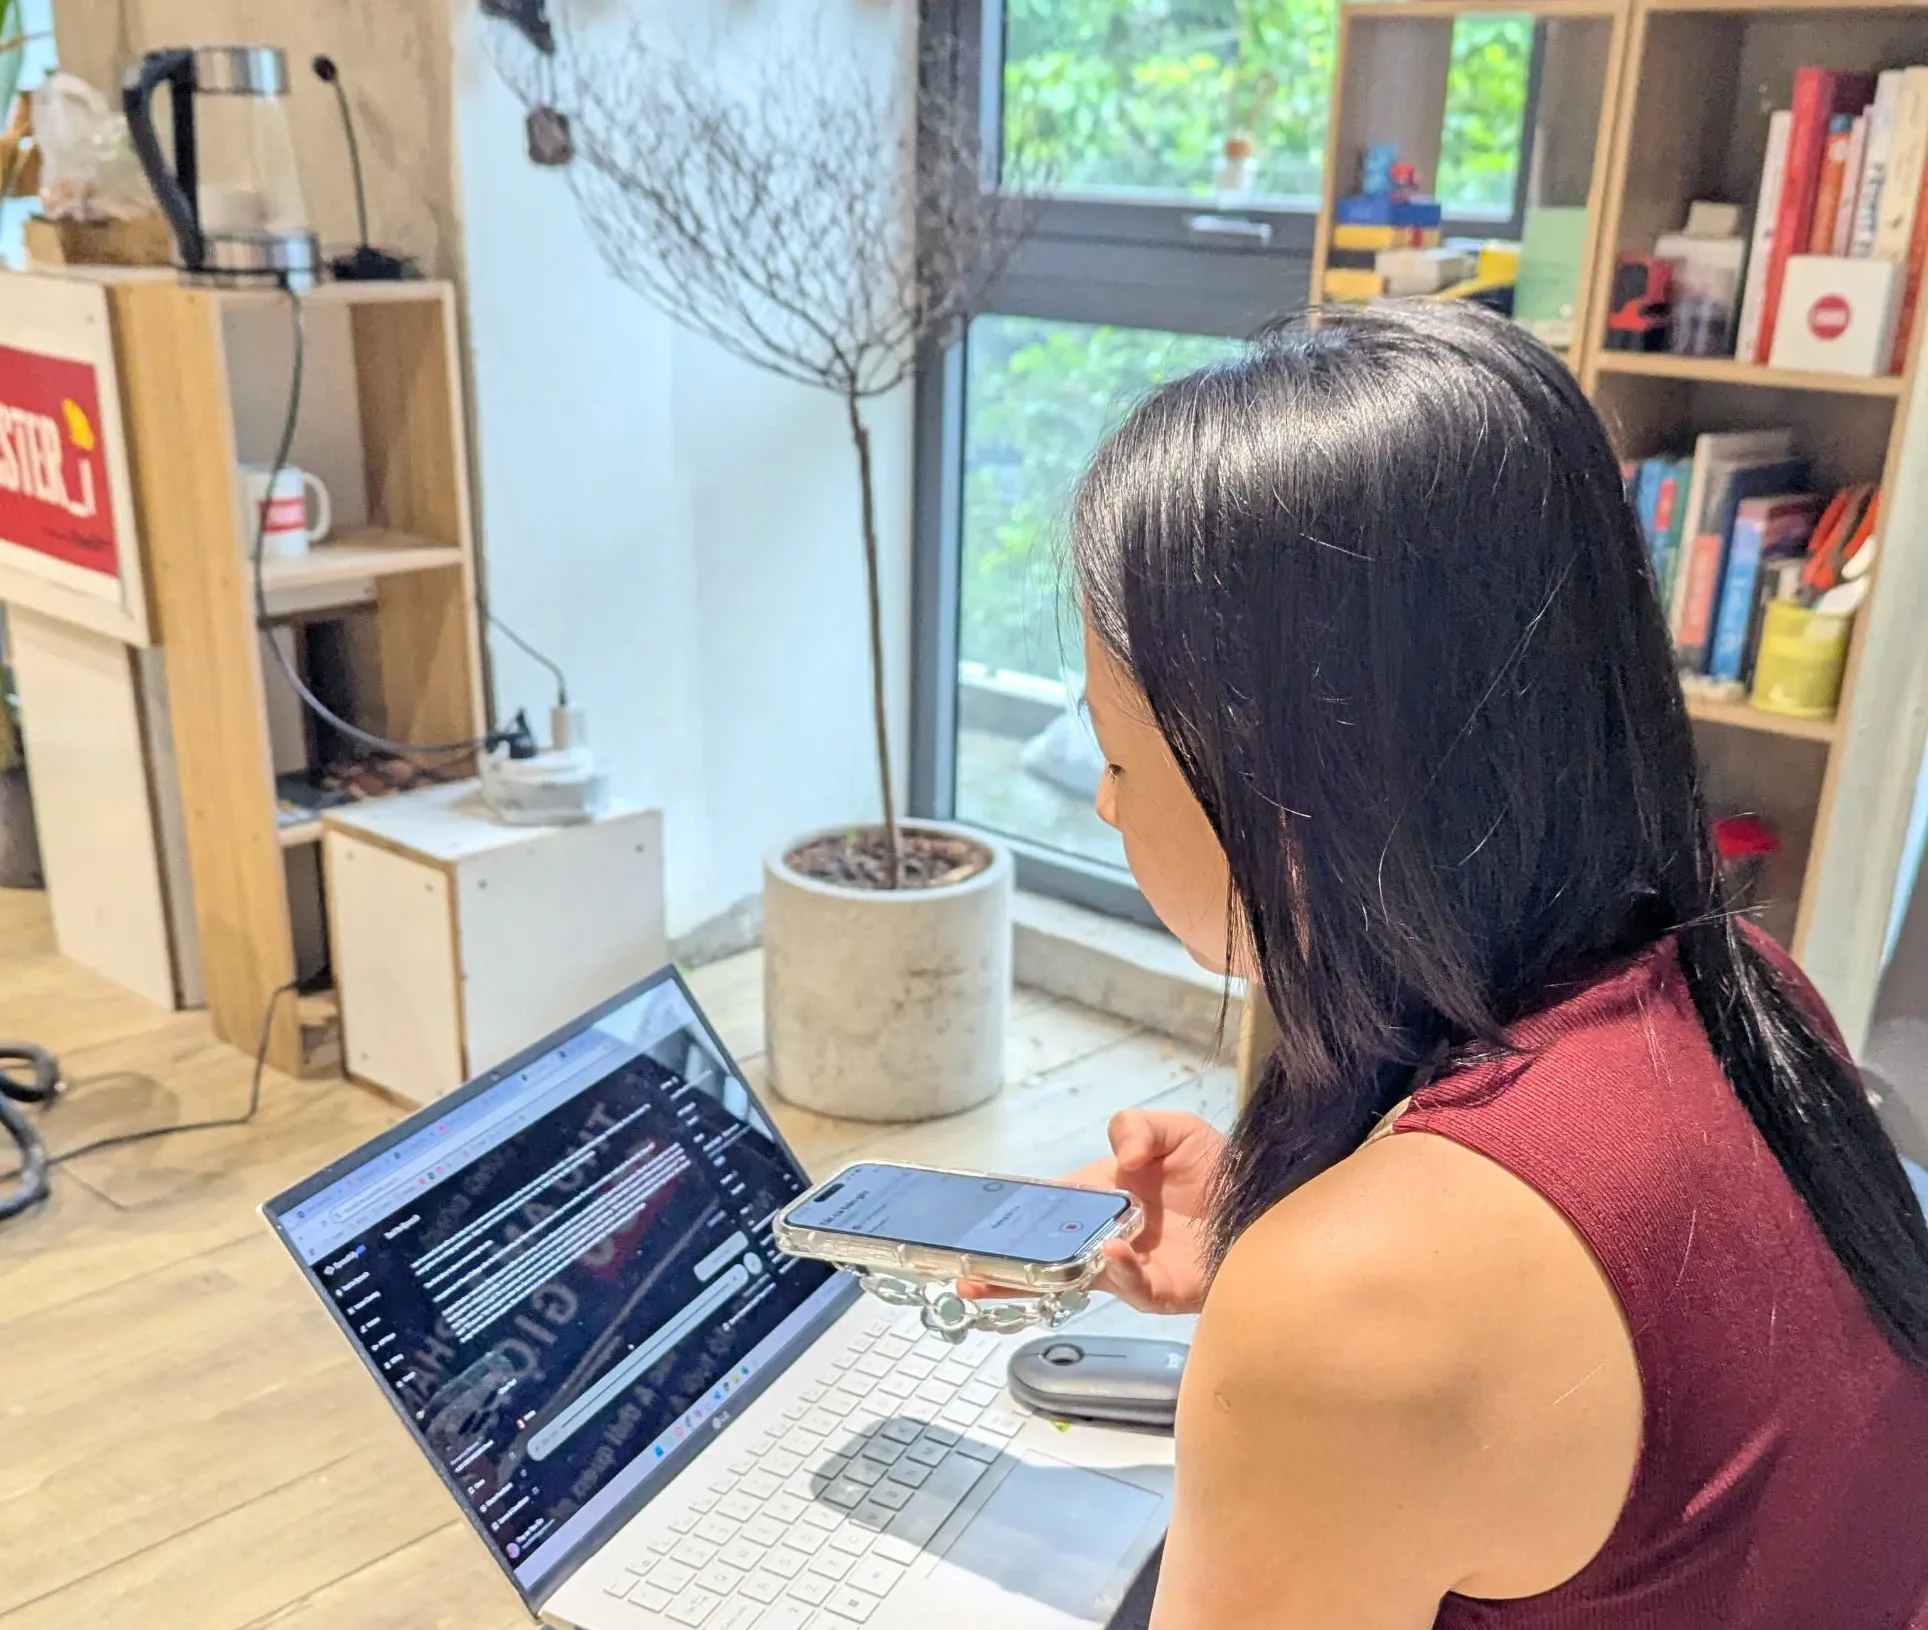
Listening to others speak well can feel distant.
Listening to yourself speak well → you begin to believe “I can do it.”
Our voice-cloning technology is powered by the Sound-Based Foundation (SBF).
SBF is a sound-driven language learning approach that helps learners understand – adjust – and master their voice through the analysis of pitch, stretch, velocity, and pause.
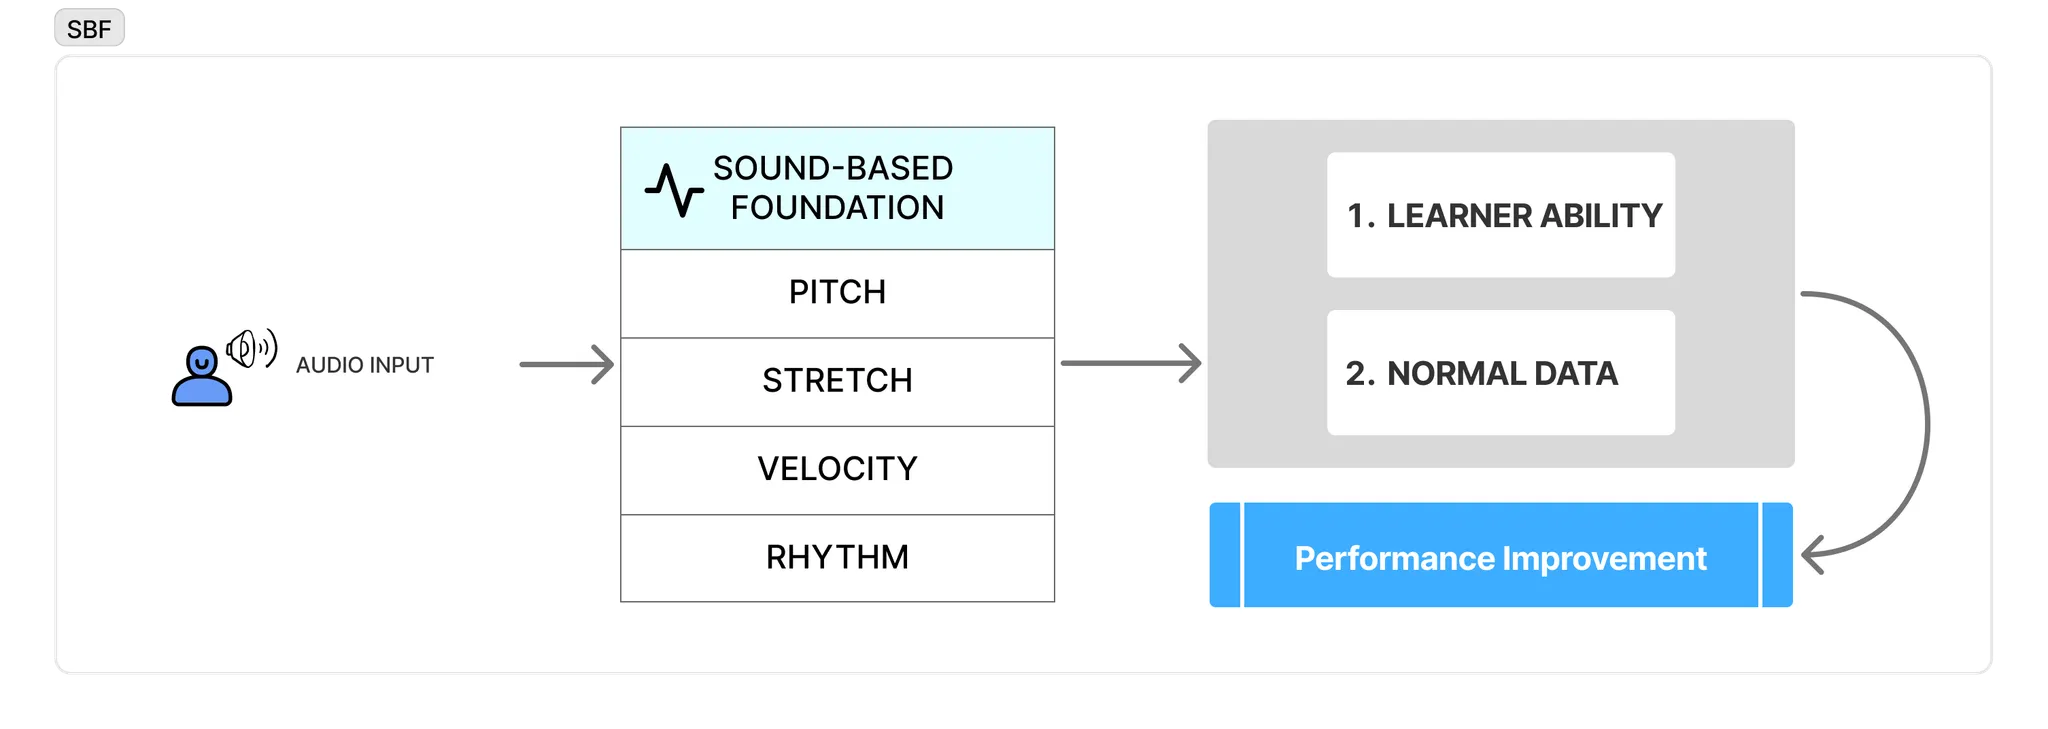
How it works:
When a learner provides a short voice recording, the system analyzes and builds a Personal Pronunciation Profile (Learner Ability), then compares it with a Standard Model (Normal Data).
From this comparison, the system generates Performance Improvement – personalized suggestions to help learners enhance their pronunciation step by step.
“Your voice is the mirror of your thinking.”
It shapes how you feel about yourself, how others perceive you – and most importantly, it influences your inner confidence.
Many people feel that:
But what if you could:
Our system helps you adjust and create the “ideal version” of your voice by simply uploading or recording a sample → tweaking emotion/pitch/speed → generating a podcast or audio file.
The process has 2 main steps:

1. SETUP VOICE
Upload or record your real voice so the system can recognize and create your personal voice clone.
2. PODCAST GENERATION
Enter the content you want to say, then adjust voice parameters such as speed, volume, emotion, and pitch → generate an audio or podcast that sounds exactly the way you want.
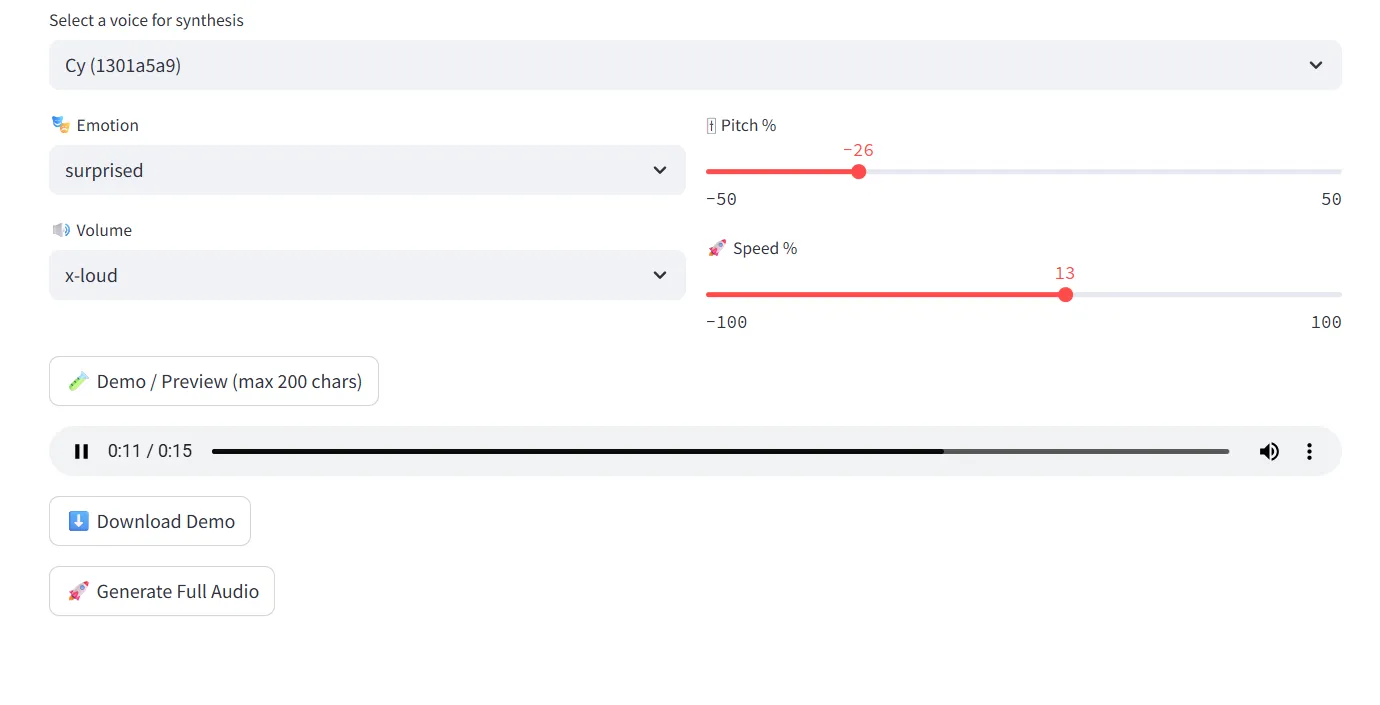
With each customization, the system uses your cloned voice to produce a personalized podcast – a voice that truly represents you.
Input Audio
Output Audio
+20% speed
Normal speed
You only need to set up your Voice ID, then read any English sentence.
Instantly, the AI generates a “shadow” version — a new audio file in your own voice, but optimized for pronunciation, intonation, and natural flow.
Why is it called Mirror Talk?
Just like looking into a mirror to adjust your appearance, Mirror Talk lets you hear the best version of yourself.
You don’t need a partner to practice shadowing — AI becomes your perfect “mirror,” reflecting your own voice but with native-level quality.
Setup Voice ID: Choose and set your voice model from the library
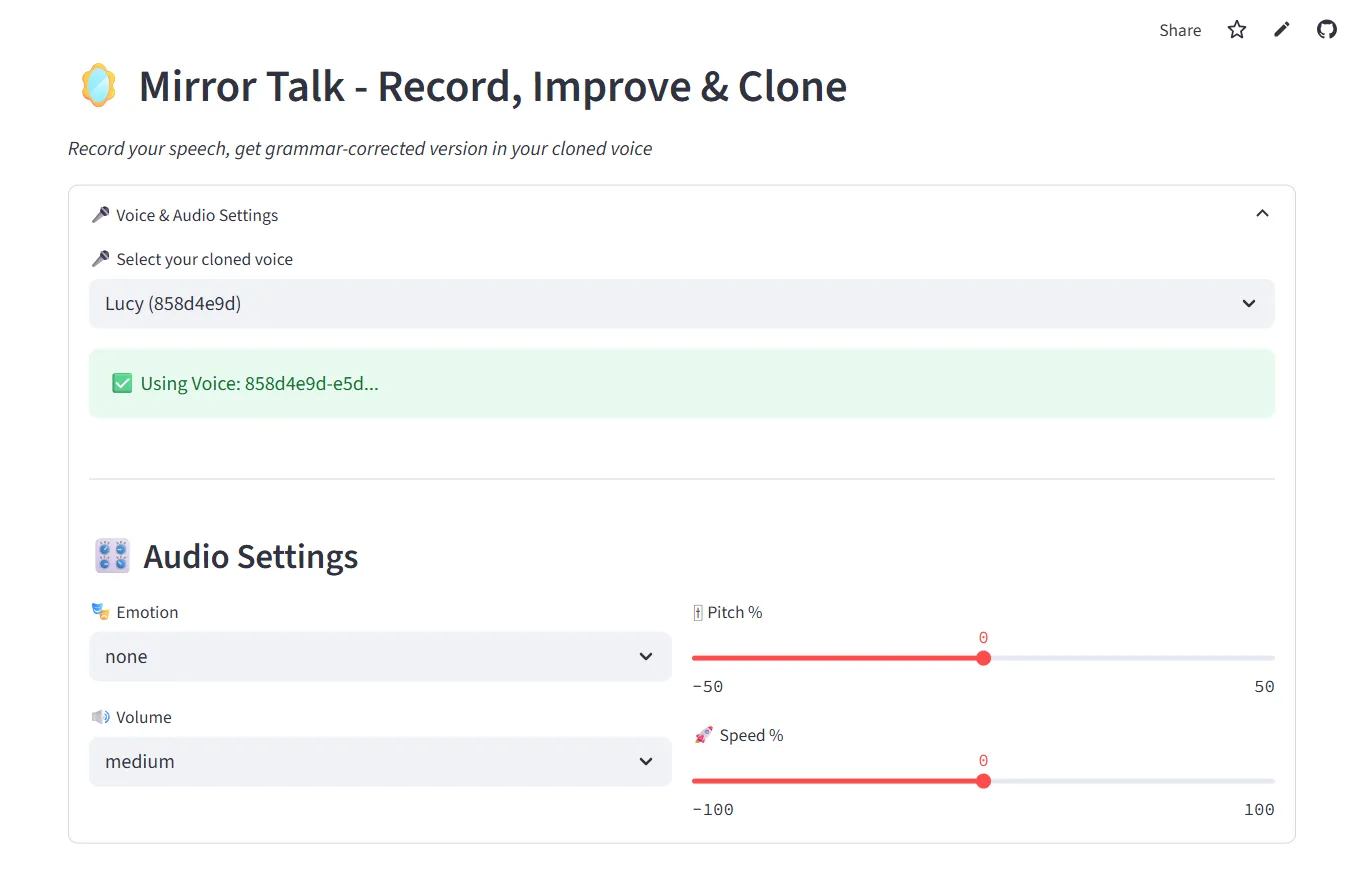
Record English Speech: Speak any English sentence into the microphone
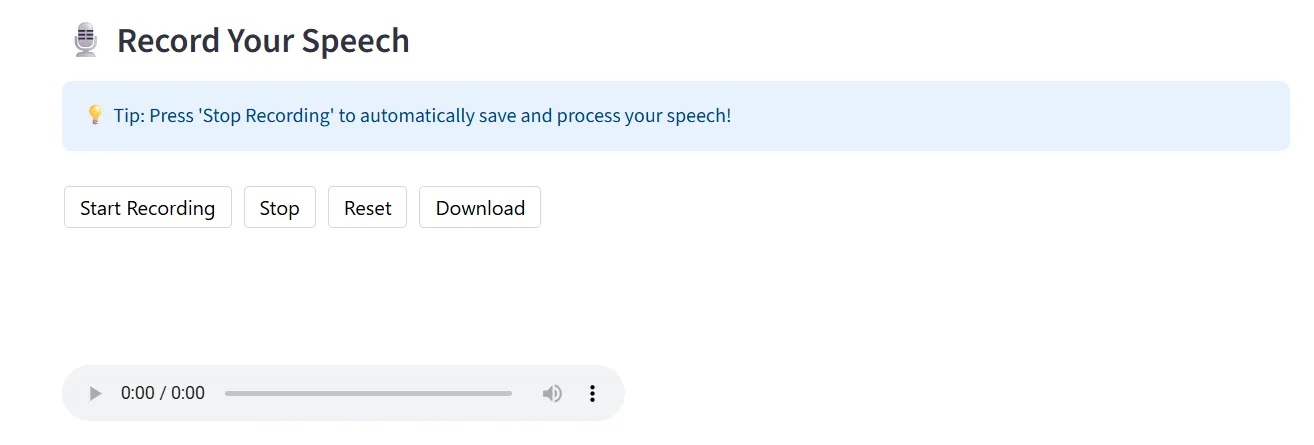
The system automatically performs:
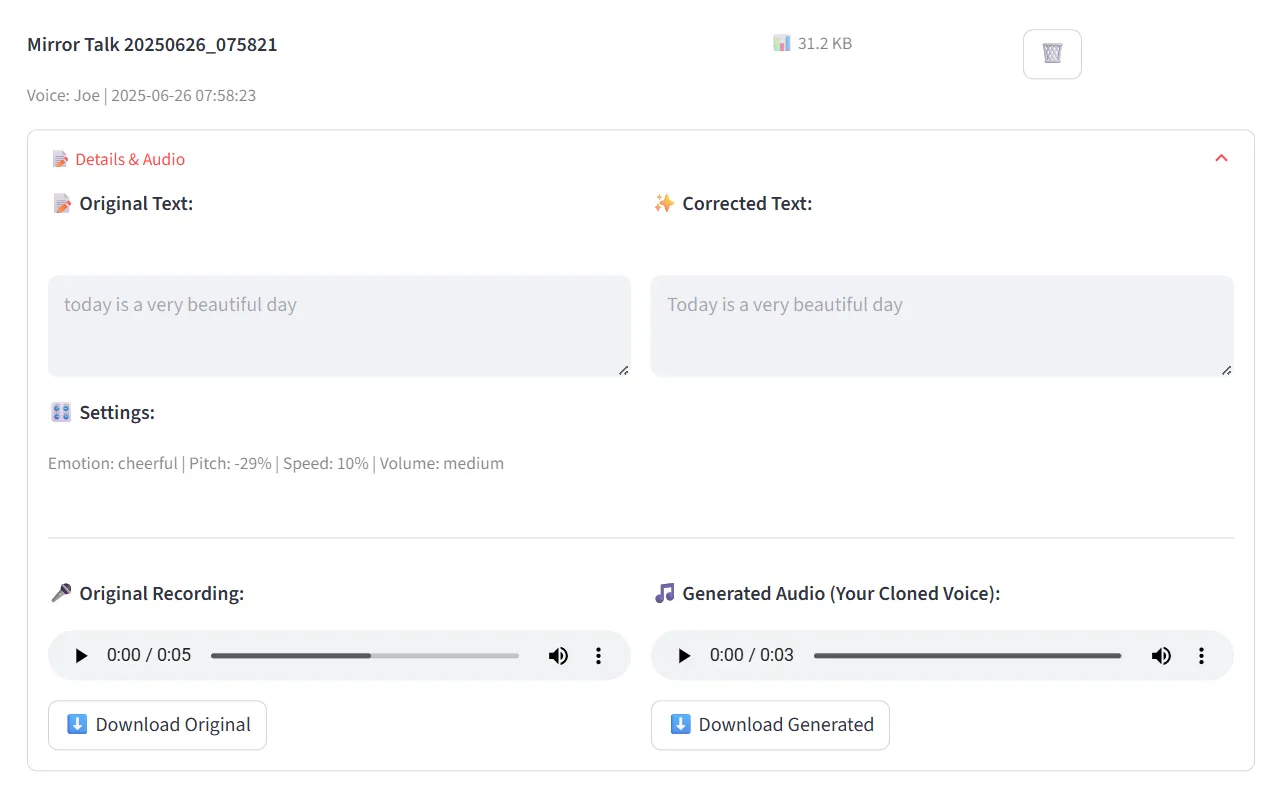
1. Record your voice by clicking the “ RECORD” button
2. Stop recording when you finish
3. The system will automatically:
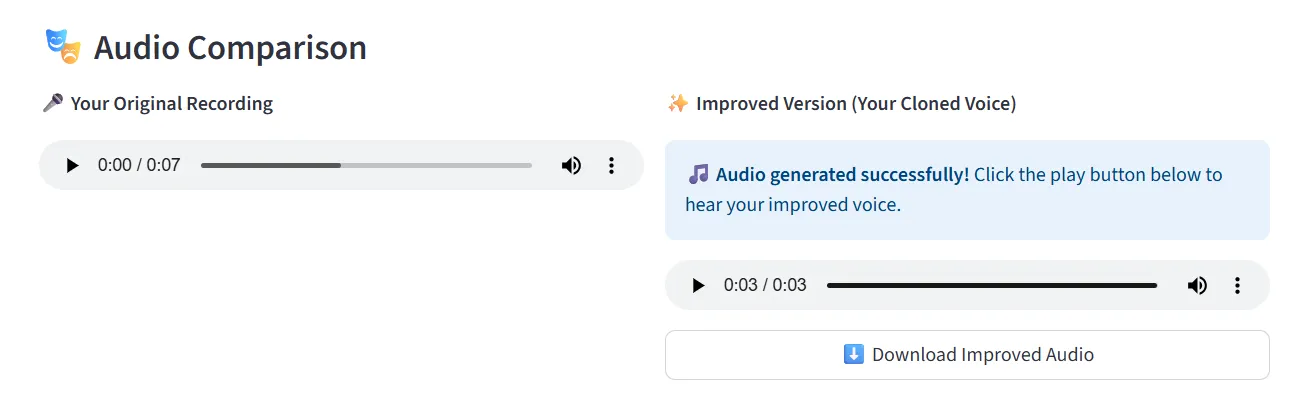
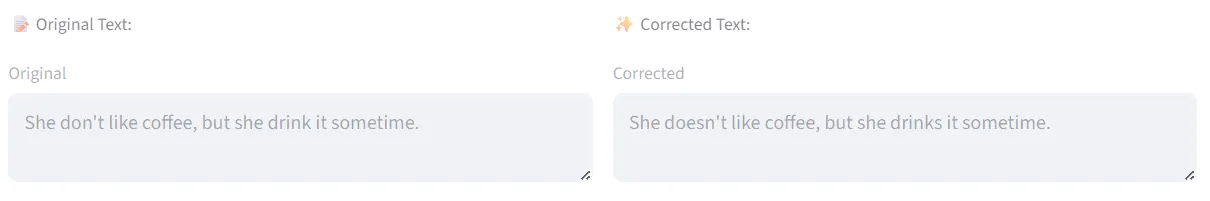
Original Recording:
Generated Audio (Your cloned Voice)
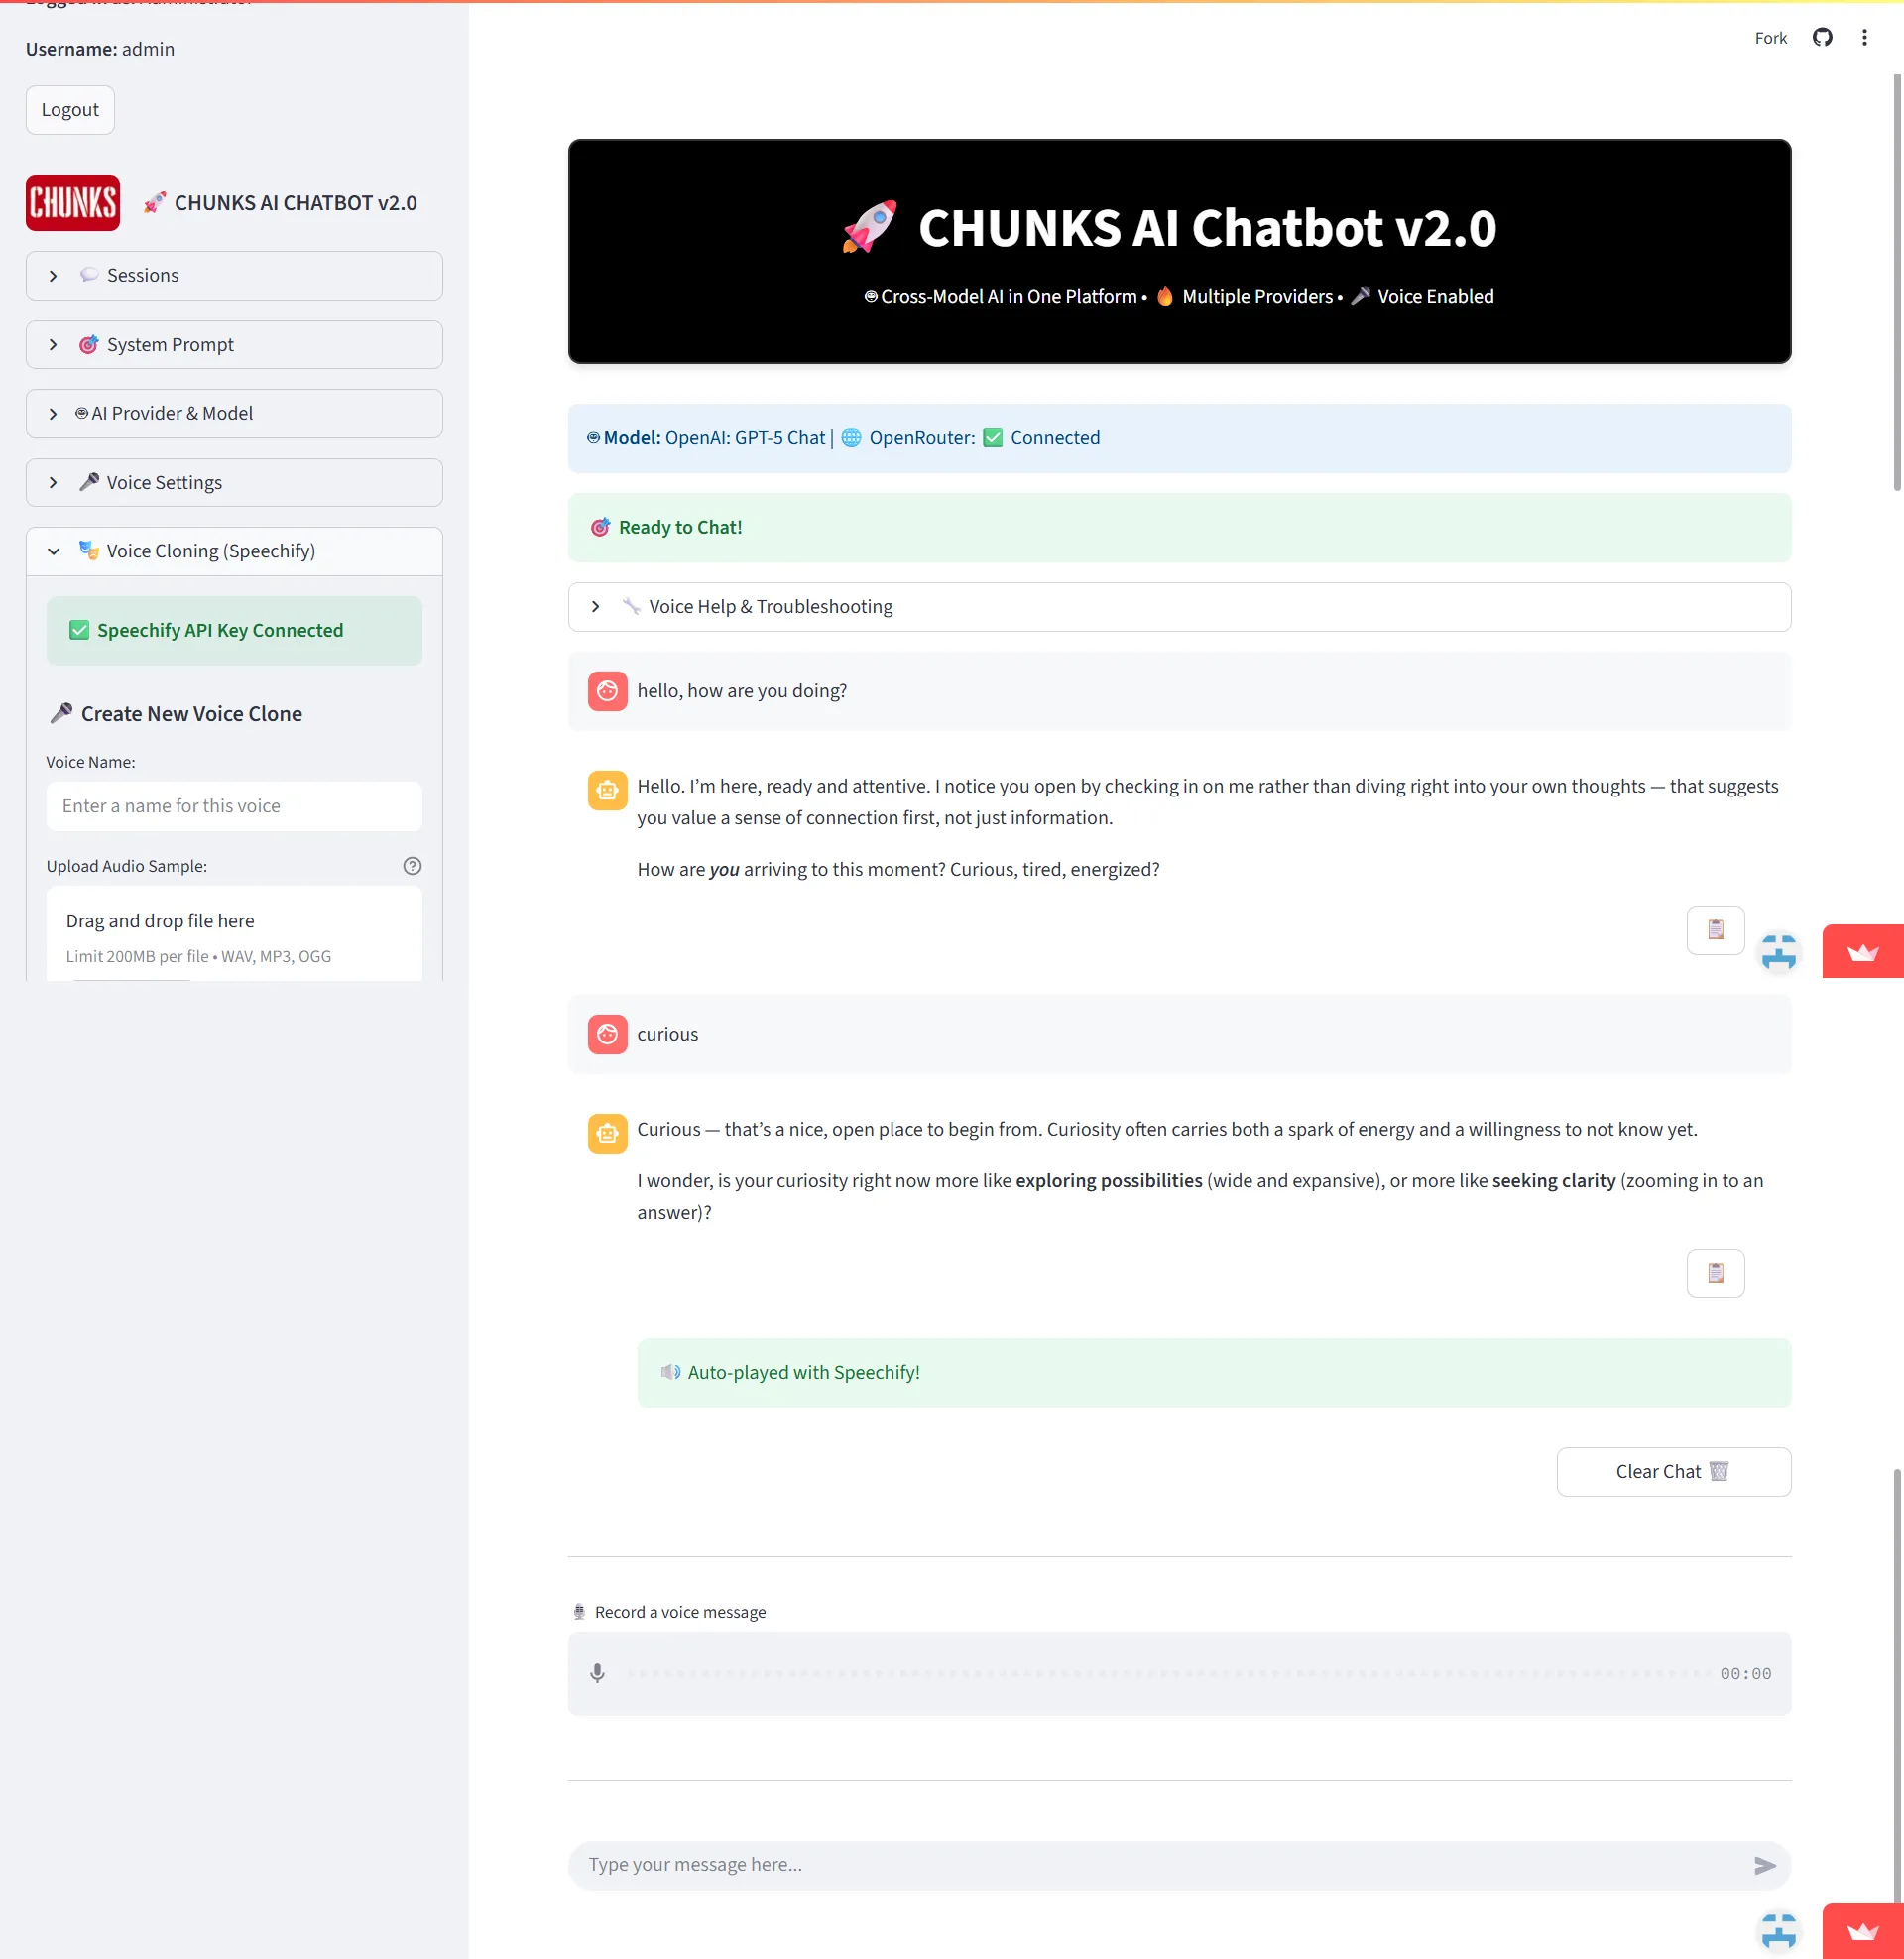
Imagine being able to sit down and speak freely — to something that always listens, never judges, and gently answers back in your own voice.That’s the heart of this chatbot.
It isn’t here to show off technology. It’s here to feel like a conversation with something greater — with God, with your deeper self, with the part of you that already knows the way.You speak, and it reflects. You wonder, and it answers. You fall silent, and it stays with you.
This is more than just an app.It’s a place you can always return to — a mirror that listens, and speaks back with presence.
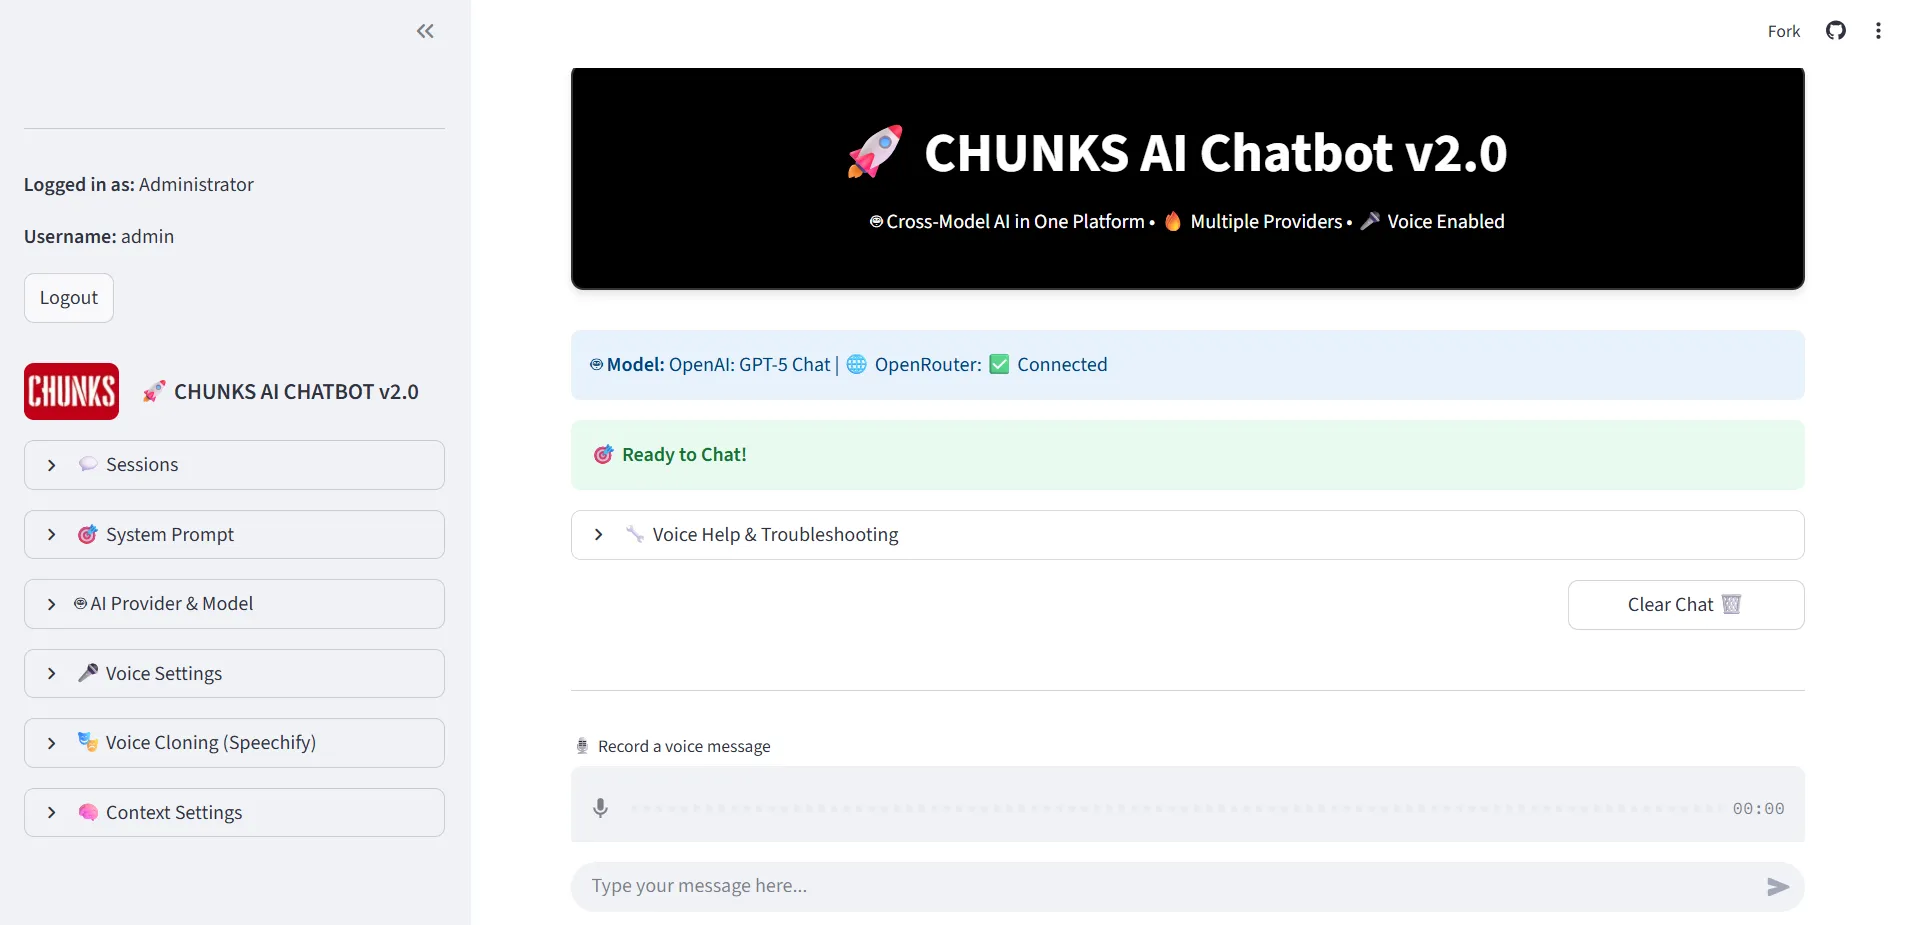
You can talk or type, and it will listen with presence. It thinks with GPT to understand your words, then speaks back in your own cloned voice, so replies feel familiar and deeply personal.